Strengthening Persona-Driven Conversational AI at Scale
Read More
AI operations outsourcing
Hugo helps AI companies build and manage dedicated human teams for model evaluation, data operations, agentic workflow testing, multilingual review, and human-in-the-loop AI training.
Built for
01Service offerings
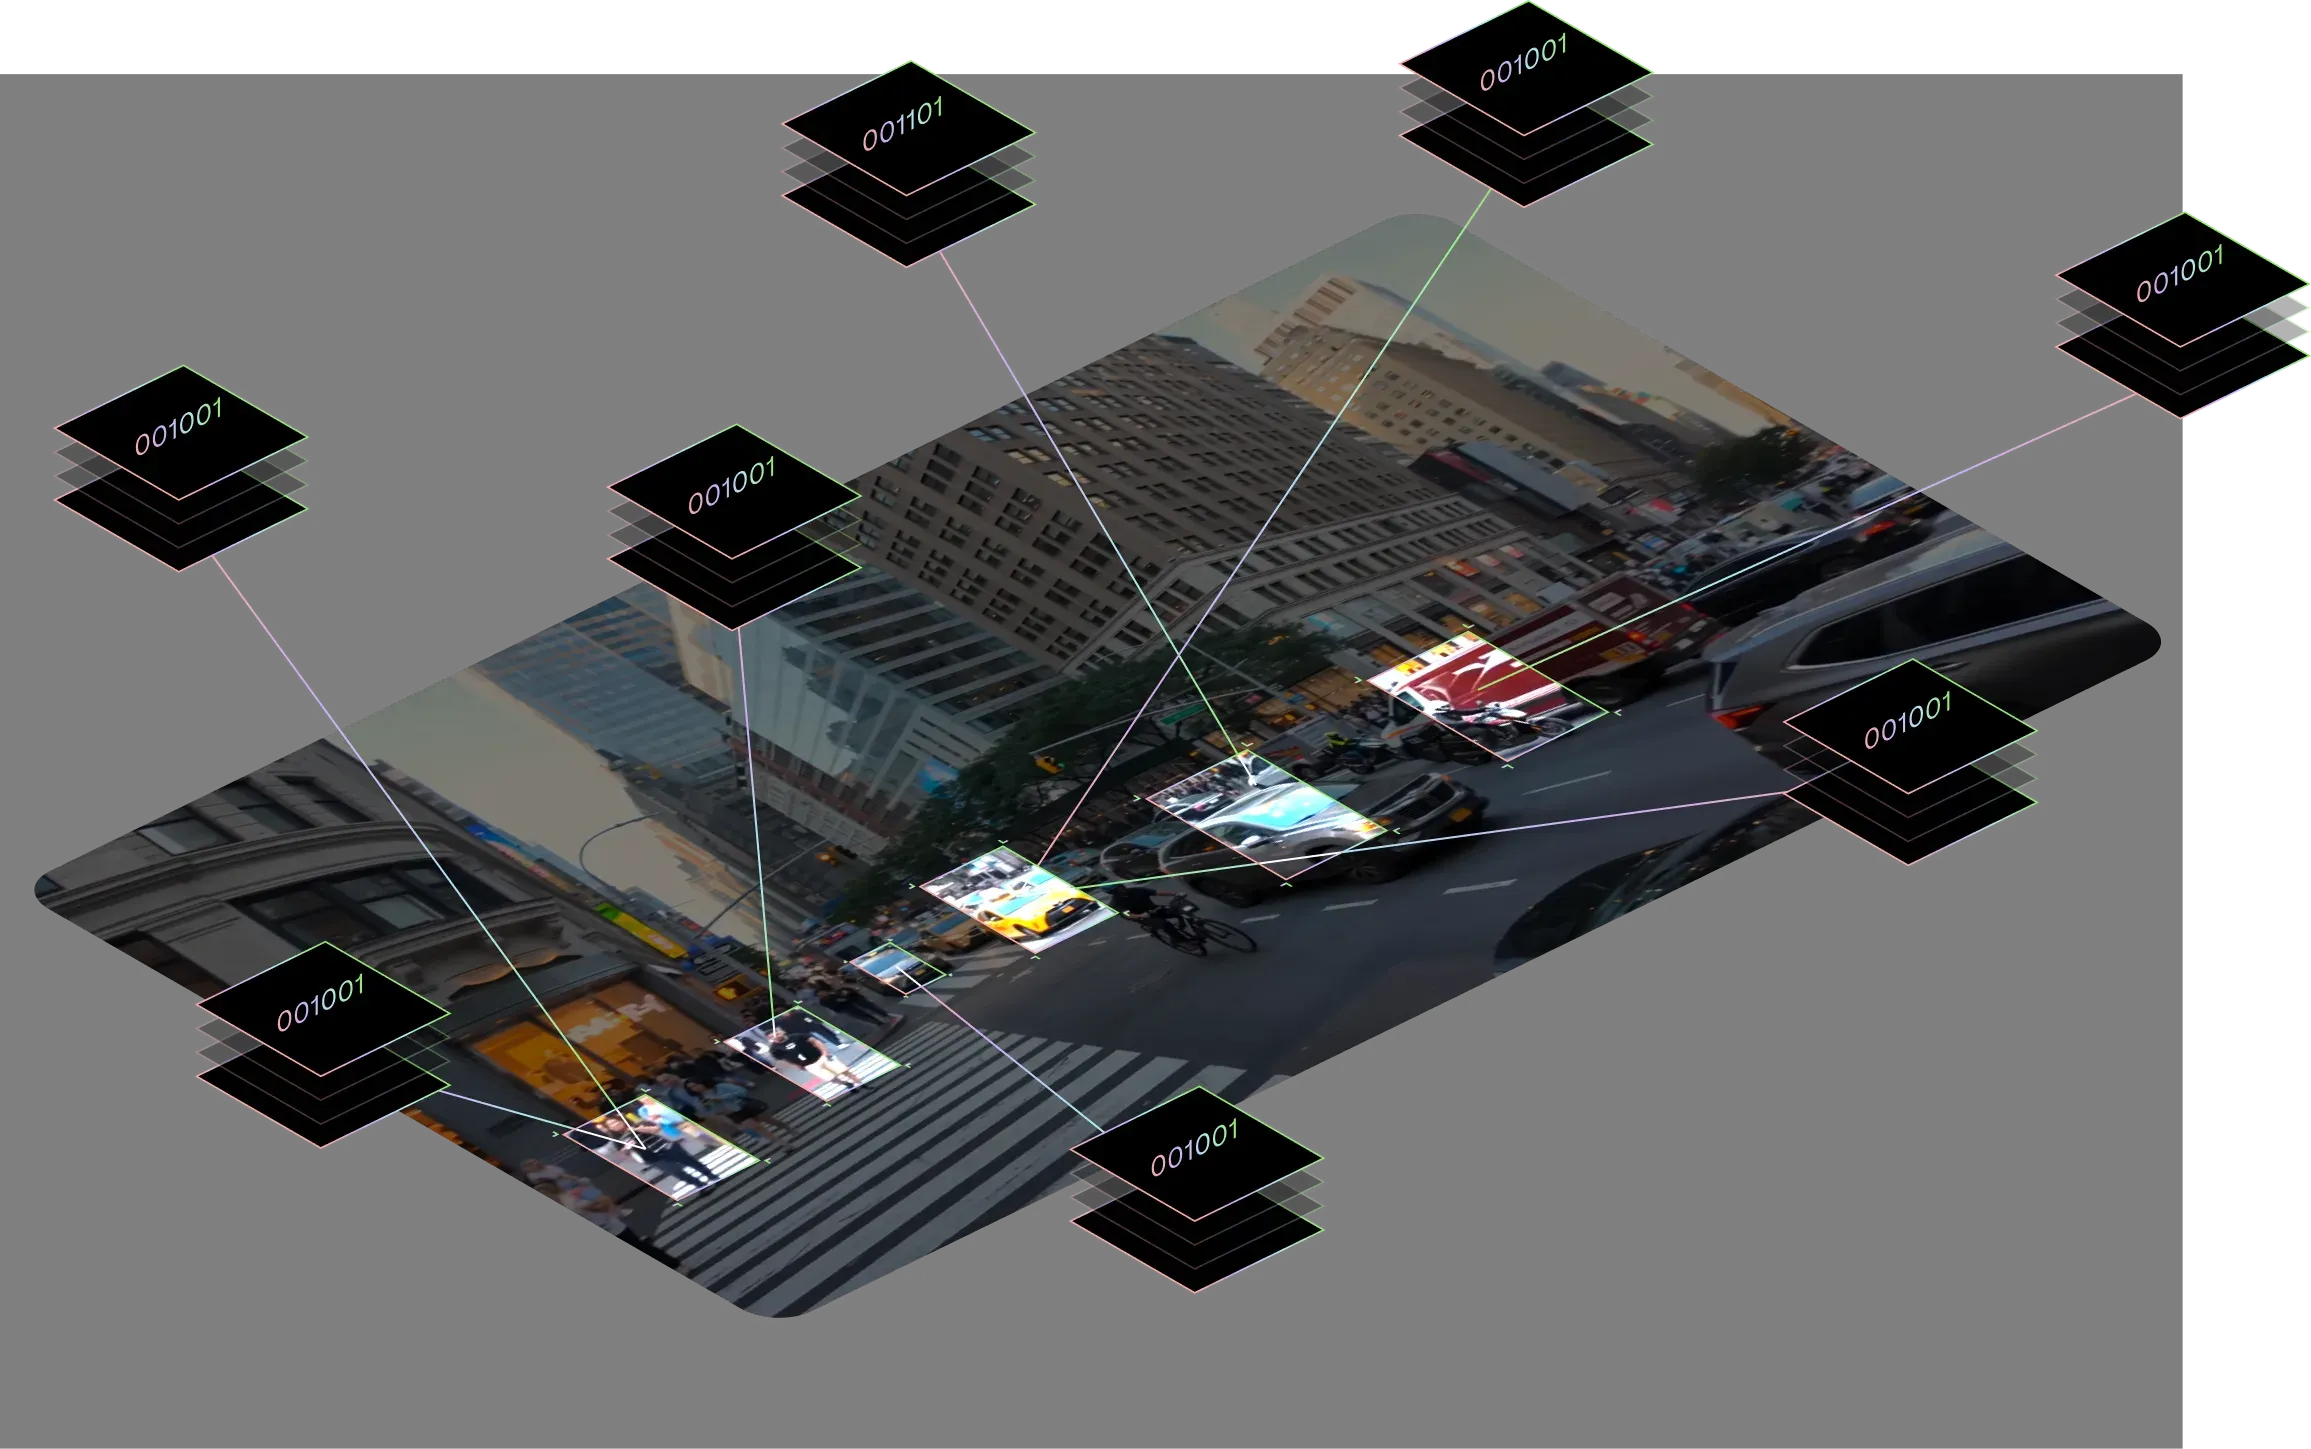
Label, review, and validate image, video, 3D, LiDAR, and cross-modal data workflows.
Learn MoreHugo’s specialists create reference responses, rank model outputs, and evaluate reasoning, safety, and alignment to support SFT, RLHF, RLAIF, and other post-training workflows.
Learn MoreTranscribe, diarize, and extract audio insights to improve speech models, voice agents, and multimodal understanding.
Learn MoreBuild and validate robotics and embodied AI datasets across sensors, environments, simulations, and real-world interactions.
Learn MoreEvaluate complex reasoning, code generation, tool use, and agentic workflows across STEM and technical domains.
Learn MoreCreate high-quality, domain-specific prompts and expert-validated evaluations to improve model accuracy and performance.
Learn More02Trusted by
10K+
Managed specialists across the globe
100+
Domain, technical, and language specializations
98%+
Quality performance across key programs
150+
Languages and dialects supported
1B+
Data points processed and reviewed
90%+
Team retention across programs
100%
Secure and compliant delivery
24/7
Global coverage and support
03Field reports
See how our teams support complex AI programs across industries, modalities, and stages of model development.
04Service offerings
Each AI workflow is built through multiple interconnected layers of human expertise. Hugo provides the teams, processes, and quality control that bring every layer to life.
Layer 01
Layer 02
Layer 03
Layer 04
Layer 05
Layer 06
05AI operations capabilities
Every AI system is only as strong as the human intelligence behind it. Hugo builds dedicated teams and 5-layer workflows to operationalize your most complex AI initiatives.
Human teams that label, review and validate images, video, 3D, LiDAR, and cross-modal data to build accurate, consistent, real-world AI systems.
Multimodal & Spatial AI
Human teams that label, review and validate images, video, 3D, LiDAR, and cross-modal data to build accurate, consistent, real-world AI systems.
Source and prepare high-quality multimodal data from image, video, LiDAR, sensors, and 3D scans.
Multi-stage QA, validation and audit checks to ensure accuracy, completeness and guideline adherence.
Structured datasets and performance insights delivered to power model training and evaluation.
Specialists annotate objects, scenes, spatial points, and taxonomies with precision and consistency.
Reviewers calibrate outputs, resolve edge cases and align on examples to reduce drift.
Hugo’s specialists create reference responses, rank model outputs, and evaluate reasoning, safety, and alignment to support SFT, RLHF, RLAIF, and other post-training workflows.
Preference Alignment & Model Post-Training
Hugo’s specialists create reference responses, rank model outputs, and evaluate reasoning, safety, and alignment to support SFT, RLHF, RLAIF, and other post-training workflows.
Specialists create and review high-quality instruction-response examples that establish reliable model behavior, formatting, and domain-specific performance.
Teams rank model responses for accuracy, helpfulness, and safety while calibrating AI-assisted judgments against human-reviewed examples for RLHF and RLAIF.
Reviewers apply scoring rubrics, check preference consistency, and audit reasoning-step labels used to train reward and process reward models.
Evaluators identify unsupported claims, unsafe responses, reward hacking, and behavioral drift to help maintain model quality throughout post-training.
Teams organize, validate, and format preference comparisons and scoring data for clients’ DPO, PPO, and GRPO training pipelines.
Transcribe, diarize, and extract audio insights to improve speech models, voice agents, and multimodal understanding.
Audio-Visual Transcription, Diarization & Acoustic Intelligence
Transcribe, diarize, and extract audio insights to improve speech models, voice agents, and multimodal understanding.
Specialists audit recordings, background noise, and voice activity boundaries to identify unusable audio before it enters model training workflows.
Reviewers verify speech-to-text outputs against source audio, correcting missing words, phonetic errors, and inaccuracies across accents and dialects.
Teams identify individual speakers, assign speaker IDs, and mark speaking turns across overlapping conversations and complex multi-speaker recordings.
Annotators identify laughter, sighs, background sounds, and other nonverbal audio events to help models understand real-world acoustic environments.
Specialists synchronize visible speakers, facial movements, and lip activity with audio streams to support speech recognition in noisy environments.
Teams apply precise timestamps, clean disfluencies when required, and structure transcripts, subtitles, and speech data according to client specifications.
Build and validate robotics and embodied AI datasets across sensors, environments, simulations, and real-world interactions.
Embodied AI & Robotics Data Infrastructure
Build and validate robotics and embodied AI datasets across sensors, environments, simulations, and real-world interactions.
Specialists audit LiDAR point clouds, camera feeds, depth maps, and sensor telemetry to identify corrupted or misaligned data.
Teams annotate 3D bounding cuboids, spatial boundaries, and camera-to-depth relationships to support accurate object positioning and environmental perception.
Annotators map objects, environments, and spatial relationships, connecting physical scenes to the natural-language instructions used by embodied AI systems.
Teams track moving objects, human actions, and physical trajectories across video frames to capture how environments change over time.
Specialists annotate hand-object-tool interactions, joint constraints, and multi-step action sequences to support imitation learning and Vision-Language-Action models.
Reviewers annotate human movement, gaze, posture, and interaction boundaries to support safer behavior in shared human-machine environments.
Evaluate complex reasoning, code generation, tool use, and agentic workflows across STEM and technical domains.
Advanced Reasoning, Agentic Coding & STEM Evals
Evaluate complex reasoning, code generation, tool use, and agentic workflows across STEM and technical domains.
Technical specialists validate isolated execution environments, dependencies, and configurations to ensure coding evaluations reflect model performance rather than setup errors.
Teams execute and review generated code, validate functional outputs, and verify unit-test results and pass@k benchmarks against expected behavior.
STEM specialists evaluate intermediate reasoning steps to detect mathematical errors, false logic, and flawed conclusions that final-answer testing may miss.
Reviewers assess repository navigation, terminal commands, tool execution, error recovery, and multi-step agent behavior across complete execution trajectories.
Senior technical specialists evaluate code quality, algorithmic efficiency, architecture, and potential security vulnerabilities beyond basic pass/fail testing.
Create high-quality, domain-specific prompts and expert-validated evaluations to improve model accuracy and performance.
STEM & Domain-Expert Prompt Generation
Create high-quality, domain-specific prompts and expert-validated evaluations to improve model accuracy and performance.
Domain specialists define topic coverage, difficulty levels, evaluation criteria, and formatting requirements to create structured prompt-generation guidelines.
STEM specialists create original mathematics, science, coding, and technical prompts designed to challenge advanced models and multi-step reasoning.
Experts develop step-by-step ground-truth answers, verifying mathematical calculations, logical reasoning, and code correctness throughout each solution.
Specialists create challenging edge cases, plausible incorrect answers, and adversarial prompts to expose weaknesses in model reasoning and safety.
Teams systematically increase prompt difficulty, introduce additional constraints, and balance topic coverage to build challenging, diverse training datasets.
Verify executable solutions, check for duplicate or benchmark-overlapping content, and prepare correctly formatted datasets for model training and evaluation.
We can build the right AI operations team around your goals, data, tools, and quality requirements.
Talk to an Expert06Team pod builder
Different AI operations require different human expertise. Hugo builds teams with the specialized agent skills needed to produce accurate, consistent, real-world results.
Evaluate and rate model outputs for quality, safety, accuracy, and alignment using complex rubrics.
Core Agent Skills
Test and validate agent behavior, tool use, code, and reasoning in sandboxed environments.
Core Agent Skills
Annotate, review, and align image, video, 3D, LiDAR, and other multimodal data with precision.
Core Agent Skills
We’ll build the right mix of skills, tools, and workflows to match your AI goals.
Build Your AI Operations Team07AI team model comparison
Hugo builds dedicated teams of evaluators, QA reviewers, and team leads trained for the workflows you need. Aligned tools, rubrics, edge cases, and quality standards help reduce drift and deliver consistent results at scale.
Fragmented, transactional, and hard to calibrate.
vs
Connected, managed, and built for long-term performance.
Team Lead (Workflow Owner)
QA & Calibration Lead (Quality & Standards)
Model Evaluation Specialists
Multilingual Reviewers
Agentic Workflow Testers
Data Operations Specialists
Build a dedicated AI operations team aligned to your workflow.
Build a Dedicated AI Operations Team08Our process
We source, train, assemble, and manage AI operations teams around your model, workflow, tools, and quality requirements. Once your team is live, Hugo continues to manage performance, calibration, and scale.
Your AI Workflow
Tools • Rubrics • Goals
Builds, trains, and manages your dedicated team
Your AI Ops Team
Aligned • Trained Managed • Scaled
We can stand up specialized AI ops teams faster than traditional hiring — typically within days to weeks, depending on the workflow and complexity.
We’re continuously developing pre-trained agents and reusable workflows to reduce the ramp time as we scale.
09Trust & security
AI operations involve sensitive data, from proprietary outputs and source code to customer information. Hugo provides secure, quality-controlled workflows that protect data without sacrificing performance.
10FAQs
Answers to common questions about how Hugo builds and manages dedicated teams for complex AI workflows.
AI operations outsourcing is the use of an external partner to build and manage human teams that support AI training, model evaluation, data operations, annotation, testing, and human-in-the-loop feedback workflows.
AI operations outsourcing is the use of an external partner to build and manage human teams that support AI training, model evaluation, data operations, annotation, testing, and human-in-the-loop feedback workflows.
AI operations outsourcing is the use of an external partner to build and manage human teams that support AI training, model evaluation, data operations, annotation, testing, and human-in-the-loop feedback workflows.
AI operations outsourcing is the use of an external partner to build and manage human teams that support AI training, model evaluation, data operations, annotation, testing, and human-in-the-loop feedback workflows.
AI operations outsourcing is the use of an external partner to build and manage human teams that support AI training, model evaluation, data operations, annotation, testing, and human-in-the-loop feedback workflows.
AI operations outsourcing is the use of an external partner to build and manage human teams that support AI training, model evaluation, data operations, annotation, testing, and human-in-the-loop feedback workflows.
AI operations outsourcing is the use of an external partner to build and manage human teams that support AI training, model evaluation, data operations, annotation, testing, and human-in-the-loop feedback workflows.
AI operations outsourcing is the use of an external partner to build and manage human teams that support AI training, model evaluation, data operations, annotation, testing, and human-in-the-loop feedback workflows.
Whether you need model evaluators, coding specialists, multilingual reviewers, or multimodal data teams, Hugo can help you build and manage the human operations layer behind better AI.
Dedicated Specialists
Quality You Can Trust
Built to Scale With You
Secure, Compliant & Reliable